react-msaview-cli
Annotate a multiple sequence alignment and render it to a publication figure, from the command line, with no browser in the loop.
The CLI has two groups of commands, and the second draws what the first writes:
- Annotate: build a domain or exon GFF for an alignment, from InterPro’s
precomputed matches (
interpro), a live InterProScan run (interproscan), or a RefSeq transcript’s exon model (genestructure), and relate rows to 3D structures (residue-mappings). - Render: draw the alignment, its tree, and those annotations to a
standalone SVG (
export-svg). The command runs the web viewer’s renderer headlessly, so the figure matches what the app shows.
Prerequisites#
- NodeJS v22+
export-svg, interpro and residue-mappings need nothing else.
interproscan needs a backend to scan with: the EBI web API (the default, no
install), Docker, Singularity, or a local InterProScan (see
interproscan).
export-svg draws the alignment background as one embedded image when
@napi-rs/canvas is present. The
package is an optional dependency with prebuilt binaries, so a normal install
brings it in. On a platform with no prebuilt binary, the export draws a
rectangle per cell, which makes a much larger file and runs slower on big
alignments.
Setup#
npm install -g react-msaview-cliFrom a clone of the monorepo instead:
pnpm install
pnpm --filter react-msaview-cli buildQuickstart#
An Src-family kinase alignment with its tree and Pfam domains, rendered in two commands. The first asks InterPro for the domains of each row; the second draws the figure.
react-msaview-cli interpro accessions.tsv -o domains.gff

react-msaview-cli export-svg --msa kinases.aln --tree kinases.nwk \
  --gff domains.gff --col-width 1.6 --row-height 14 --tree-area-width 200 \
  -o kinases.svg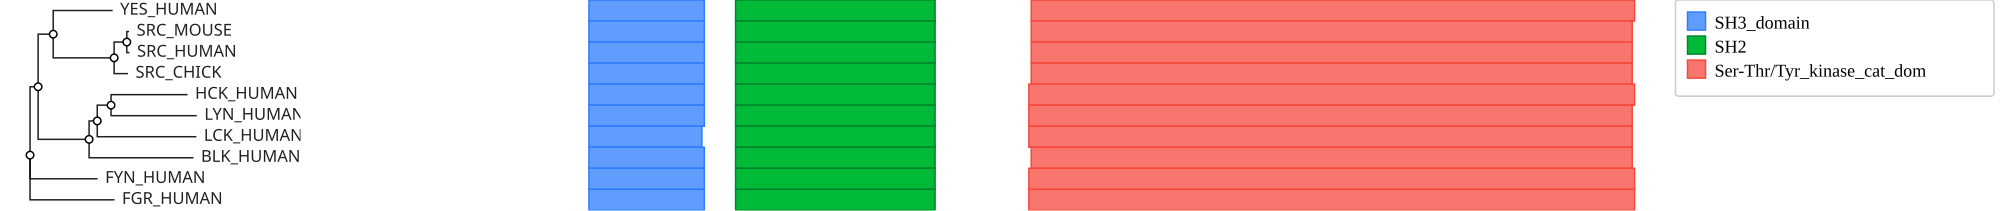
Every figure on this page is export-svg output, drawn from the Src-kinase and
GPCR examples in
packages/examples.
Rendering figures#
react-msaview-cli export-svg --msa <file> [options]| Option | Description | Default |
|---|---|---|
--spec <file.json> | View spec or snapshot (see below) | |
--msa <file> | MSA file (FASTA, Stockholm, Clustal, A3M, EMF) | required |
--tree <file> | Newick tree file | |
--gff <file> | Domain or exon GFF, or InterProScan JSON | |
-o, --output <file> | Output SVG file path | alignment.svg |
--color-scheme <name> | Color scheme | maeditor |
--col-width <px> | Width of one alignment column | 12 |
--row-height <px> | Height of one alignment row | 16 |
--width <px> | Viewport width, which sets the tree area | 1200 |
--height <px> | Viewport height | 600 |
--tree-area-width <px> | Tree panel width in pixels | |
--format <name> | Force the MSA format instead of sniffing it | |
--tracks <list> | Tracks to draw above the alignment, by id | none |
--viewport | Draw the viewport instead of the whole thing | |
--minimap | Include the minimap bar (--viewport only) |
Tracks#
--tracks names the tracks to draw above the alignment, by id, or all for
every one this alignment has: conservation, property-conservation (protein
only), sequence-logo, position-ruler, base-pairs (a Stockholm SS_cons
line), and any track ids the file itself carries. The CLI reports a name that
matches no track.
react-msaview-cli export-svg --msa kinases.aln --tracks conservation,position-ruler \
-o kinases.svgLayers#
--spec takes an MsaView snapshot or its shorthand as a JSON file, so any
layer in the layers reference draws in the
figure: column tracks, highlights, clades, row panels, encodings. A spec that
sets msa, tree, or a filehandle’s uri to a relative path reads it beside
the spec file, and an http(s) one fetches it. --msa is then optional, and
every flag given on the command line overrides the spec. The figure draws the
tracks the app would show for the spec, unless --tracks names them.
react-msaview-cli export-svg --spec p53-view.json -o p53.svgSizing the figure#
export-svg draws the entire alignment unless --viewport asks for the
--width x --height window at the top left, so the output is normally as wide
as the alignment is long. --width and --height size the viewport the model
lays out in, not the figure. --col-width and --row-height scale the figure:
## a 90-column alignment at the default 12px columns: letters are legible
react-msaview-cli export-svg --msa gpcrs.fa -o gpcrs.svg
## an 856-column alignment at 1.4px columns: an overview, no letters
react-msaview-cli export-svg --msa kinases.aln --tree kinases.nwk \
  --col-width 1.4 --row-height 16 --tree-area-width 280 -o overview.svg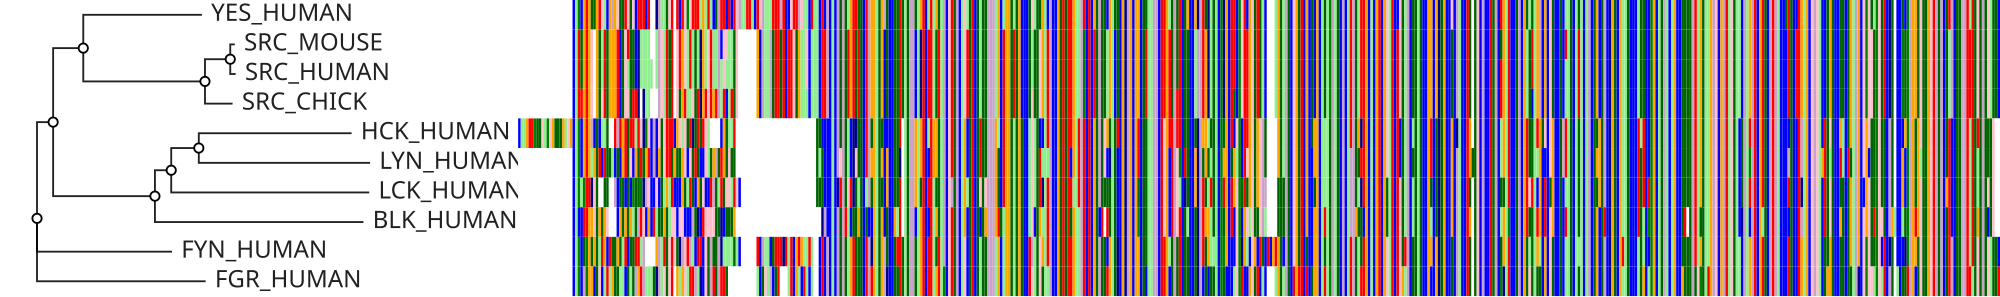
Color schemes#
react-msaview-cli export-svg --msa gpcrs.fa \
  --color-scheme clustalx_protein_dynamic -o gpcrs.svg
maeditor (the default), clustal, clustalx_protein, lesk, flower,
cinema, and the jalview_* family (jalview_zappo, jalview_taylor,
jalview_hydrophobicity, jalview_buried, jalview_prophelix,
jalview_propstrand, jalview_propturn) color each residue by identity. The
two _dynamic schemes, clustalx_protein_dynamic and
percent_identity_dynamic, color each residue by the composition of its column,
so conserved columns stand out by color. nucleotide, clustalx_dna,
jbrowse_dna and rainbow_dna are for DNA; none turns background color off.Output#
The SVG grows with the alignment: a 10-row by 856-column figure is about 700KB. The background is one embedded image where @napi-rs/canvas is installed, and a rectangle per cell where it is not. The letters, the tree and the annotations are vector either way. To convert to PNG or PDF for a journal:
rsvg-convert -w 2000 alignment.svg -o alignment.png
inkscape alignment.svg --export-filename=alignment.pdf
The same input gives the same bytes, so CI can regenerate a figure and diff it.
Annotating#
interpro#
Build a domain GFF from InterPro’s precomputed matches for UniProtKB
accessions. The EBI InterPro API already serves matches for every UniProtKB
sequence, so the lookup returns in seconds, gives the same result for a given
InterPro release, and needs no email or rate-limited job. Use this instead of
interproscan whenever your rows are UniProt accessions.
react-msaview-cli interpro <accessions.tsv> [options]The input is one accession per line, optionally followed by a tab- or
space-separated row label. The command skips lines starting with #. It reads
an isoform (P04637-2) or versioned (P04637.4) accession as the canonical one
and warns, and stops before any request on an entry name (P53_HUMAN), a RefSeq
id or anything else InterPro does not key by; run interproscan on those. It
writes through the same GFF writer as interproscan, and adds a # header line
naming the InterPro release the coordinates came from.
| Option | Description | Default |
|---|---|---|
-o, --output <file> | Output GFF file path | domains.gff |
--database <name> | InterPro member db to read | pfam |
--msa <file> | Alignment to check the rows of (see below) | |
--format <name> | Force the --msa format instead of sniffing it | |
--no-cache | Re-fetch, ignoring the disk cache | off |
InterPro computes matches on UniProt’s canonical sequence. A label ending in
/start-end, as Pfam and Stockholm name a fragment row (P12931/84-145), moves
each match into the fragment’s own positions and clips it to the fragment. On an
isoform row the matches land on the wrong residues. With --msa, the CLI
compares each row’s ungapped length against the protein’s, or against the
range’s for a fragment, and warns about any that differ. It also warns about any
accession with no matches.
react-msaview-cli interpro accessions.tsv -o domains.gff
react-msaview-cli interpro accessions.tsv -o domains.gff --database cddCaching#
The InterPro API serves one protein per request and has no batch endpoint, so a
run makes one request per distinct accession. The CLI caches every response on
disk under $XDG_CACHE_HOME/react-msaview-cli/interpro (override with
REACT_MSAVIEW_CACHE), keyed by InterPro release, so a new release fetches
fresh coordinates. The cache also records proteins with no matches, so a re-run
does not fetch them again.
A re-run of the same dataset makes one request, the release lookup, and reads the rest from disk. A failed run can therefore resume. The CLI retries with backoff, and if the API stays unreachable, the accessions it already fetched stay cached, so the next run fetches only the rest.
When the release lookup fails, the CLI warns and reads the newest release in the cache, so a fully cached run needs no network.
interproscan#
Run InterProScan on all sequences in an MSA file and output results as GFF3. Use this when the rows are not UniProt accessions: a de novo assembly, predicted proteins, or anything else InterPro has not scanned.
react-msaview-cli interproscan <input-msa> [options]| Option | Description | Default |
|---|---|---|
-o, --output <file> | Output GFF file path | domains.gff |
--local | Use a local InterProScan installation instead of EBI | false |
--docker | Run InterProScan via the interpro/interproscan image | false |
--singularity | Run InterProScan via a Singularity/Apptainer container | false |
--docker-image <img> | Docker image to run | interpro/interproscan:5.78-109.0 |
--singularity-image <img> | Singularity image to use | docker://interpro/interproscan:5.78-109.0 |
--interproscan-path <path> | Path to local interproscan.sh | interproscan.sh |
--interproscan-data <dir> | Member database data/ to mount into the container | |
--programs <list> | Comma-separated list of programs, in EBI API naming | PfamA,CDD |
--format <name> | Force the MSA format instead of sniffing it | |
--email <email> | Email for EBI API (used only for EBI API runs) | user@example.com |
By default (no backend flag) the CLI submits sequences to the EBI InterProScan
REST API one at a time. --local, --docker, and --singularity run
InterProScan on the whole alignment locally, which is much faster for large
datasets.
Choosing a backend#
## EBI web API: no install, one sequential submission per sequence
react-msaview-cli interproscan alignment.fasta -o domains.gff --email you@example.com

## Docker: no InterProScan install, whole alignment in one run
react-msaview-cli interproscan alignment.fasta -o domains.gff --docker

## a local install
react-msaview-cli interproscan alignment.fasta -o domains.gff \
  --local --interproscan-path /opt/interproscan/interproscan.sh

## Singularity/Apptainer, for HPC clusters without Docker
react-msaview-cli interproscan alignment.fasta -o domains.gff \
  --singularity --singularity-image /path/to/interproscan.sif
Docker mounts a temp directory into the interpro/interproscan container, runs
the scan on the whole alignment at once, and reads the JSON back out.
The published image carries InterProScan but not its member database data,
which is a separate multi-gigabyte download. Fetch and unpack the matching
release’s data/ directory (see the
InterProScan docs) and point
--interproscan-data at it. Both container backends mount it at
/opt/interproscan/data and look for it there.
The EBI API has usage limits, so the CLI submits sequences one at a time. Past about 100 sequences, use a local or container backend.
InterProScan programs#
--programs takes the EBI API’s names whichever backend runs: PfamA and CDD
(the default), SMART, SuperFamily, Gene3d, PANTHER, TIGRFAM, HAMAP,
PrositeProfiles, PrositePatterns, PRINTS, PIRSF, MobiDBLite, Coils,
SFLD. InterProScan 5 spells several of them differently (Pfam, not PfamA;
NCBIfam, which absorbed TIGRFAM; Hamap; SUPERFAMILY; Gene3D), and the
CLI passes the translated names to the local, Docker and Singularity backends.
react-msaview-cli interproscan alignment.fasta -o domains.gff \
--programs PfamA,SMART,Gene3D --email you@example.comgenestructure#
Build a gene-structure GFF for a coding-sequence alignment from a RefSeq
transcript, overlaid the same way InterProScan domains are. The command fetches
the exon model from the NCBI Datasets v2 API and names each species’ Nth exon
exon-N, so a given exon is the same color in every row and the exon
architecture reads straight down the alignment.
react-msaview-cli genestructure <input-msa> --gene <symbol> --ref <rowname> [options]The command maps the chosen transcript’s exon boundaries onto the reference row’s columns, then projects them into every other row’s ungapped coordinates. An exon that picks up a frameshifting indel in one lineage therefore gets shorter on that row and stays in the same columns as the rest. The reference row must be the transcript’s coding sequence; the CLI warns if its length doesn’t match.
| Option | Description | Default |
|---|---|---|
--gene <symbol> | Gene symbol to look up in RefSeq (e.g. F12) | |
--taxon <name|id> | Taxon for --gene | human |
--gene-id <id> | NCBI GeneID, instead of --gene | |
--transcript <acc> | Specific transcript accession | MANE/RefSeq Select |
--ref <rowname> | Reference row = the transcript’s CDS | first row |
-o, --output <file> | Output GFF file path | genestructure.gff |
## F12 coding alignment -> 14-exon overlay (MANE Select transcript, human row)
react-msaview-cli genestructure f12-cds.stock --gene F12 --ref human -o exons.gff

## pin a specific transcript
react-msaview-cli genestructure aln.fa --transcript NM_000505.4 --ref humanresidue-mappings#
Build the
residueMappings layer,
which tells the viewer which residue of a PDB chain or an AlphaFold model each
residue of a row is. The output is {"residueMappings": [...]}, ready for the
residueMappings prop, a #data= link, or the R and Python widgets.
react-msaview-cli residue-mappings --msa <file> --row <name> --accession <acc> \
  (--pdb <id> --chain <id> | --alphafold) [-o mappings.json]
react-msaview-cli residue-mappings --msa <file> --rows <tsv> [-o mappings.json]| Option | Description | Default |
|---|---|---|
--msa <file> | Alignment holding the rows | |
--format <name> | Force the MSA format instead of sniffing it | |
--rows <tsv> | row, accession, structure per line, tab-separated | |
--row <name> | One row, instead of --rows | |
--accession <acc> | The row’s UniProtKB accession | |
--pdb <id> --chain <id> | The PDB entry and its author chain | |
--alphafold | The AlphaFold DB model of the accession instead | |
-o, --output <file> | Output JSON file | stdout |
In --rows, the structure column is 6VXX:A or alphafold, and a
row accession structure header line is optional. A row may appear on several
lines to map it onto several structures.
For each row, the CLI first fetches the accession’s sequence from UniProt and
checks the row’s ungapped residues against it. A row named /start-end has to
match that slice of the protein, and every position in its mapping is a residue
of the row. A mismatch stops the run with the row, the accession and the first
residue where they differ.
For a PDB chain, the segments come from the PDBe SIFTS mapping of the entry, and
unobserved lists every position of the chain’s entity outside PDBe’s observed
ranges. asymId is the struct_asym_id SIFTS gives for the author chain. For
an AlphaFold model, the model numbers the protein from 1, so the mapping is one
segment and has no unobserved.
$ react-msaview-cli residue-mappings --msa spike.afa --row SARS-CoV-2 \
    --accession P0DTC2 --pdb 6VXX --chain A -o mappings.json
  SARS-CoV-2: P0DTC2 onto 6VXX chain A, row 14-1211 at 33-1230
wrote mappings.json
Input formats#
The CLI sniffs the format from the file’s content, not from its name. --format
(fasta, a3m, stockholm, clustal, emf) overrides a wrong guess. FASTA
and A3M share a leading >, so the CLI tells them apart heuristically.
- FASTA (
.fasta,.fa,.faa) - Clustal (
.clustal,.aln) - Stockholm (
.sto,.stockholm) - A3M (
.a3m), from AlphaFold/ColabFold - EMF (
.emf), Ensembl Multi Format
Annotation output format#
The annotation commands write standard GFF3, one line per feature:
protein_match for a domain from interpro/interproscan, exon for a
segment from genestructure. start/end are 1-based positions in the
ungapped sequence, and the attributes carry the accession, name, and
description:
##gff-version 3
seq1	InterProScan	protein_match	10	150	.	.	.	Name=PF00001;signature_desc=7tm_1;description=7 transmembrane receptor (rhodopsin family)
seq1	InterProScan	protein_match	200	350	.	.	.	Name=PF00002;signature_desc=7tm_2;description=7 transmembrane receptor (Secretin family)
seq2	InterProScan	protein_match	5	120	.	.	.	Name=PF00001;signature_desc=7tm_1;description=7 transmembrane receptor (rhodopsin family)
A worked run:
$ react-msaview-cli interproscan gpcrs.fasta -o domains.gff --docker
Reading MSA from gpcrs.fasta...
Found 4 sequences
Processing 4 non-empty sequences...
  Running InterProScan via Docker on 4 sequences...
  docker run --rm -v /tmp/interproscan-Xyz12:/data -v /opt/interproscan-5.78-109.0/data:/opt/interproscan/data interpro/interproscan:5.78-109.0 -i /data/input.fasta -o /data/output.json -f JSON -appl Pfam,CDD
Converting results to GFF...
Writing output to domains.gff...
Done!
Using the GFF elsewhere#
The web viewer, the React component and the R package all load the file the CLI writes.
In the web viewer, select it in the import form’s Annotation GFF file or URL field, or open it over a loaded alignment with Annotations > Open annotation file…, which also accepts the JSON an InterProScan run returns.
In the React component, pass it inline as the gff prop:
<MSAViewer msa={msaText} gff={domainsGff} />From R:
msaview(msa = "alignment.fasta", gff = "domains.gff")Troubleshooting#
EBI API timeout. We measured one sequence waiting fifteen minutes in the
queue. The CLI waits an hour per job and keeps the results of the sequences that
finished. Use --local, --docker, or --singularity to run InterProScan
yourself; on large datasets they are much faster than the API.
Local InterProScan not found.
Error: Failed to run Local: spawn interproscan.sh ENOENT. Is interproscan.sh installed and on PATH?Give the full path:
--interproscan-path /full/path/to/interproscan-5.xx/interproscan.sh
No results in the output. Check that the sequences are protein, not
nucleotide; try other --programs; verify the input parses as one of the
formats above.
The exported figure is enormous. export-svg draws the whole alignment at
--col-width per column. Lower --col-width until it fits. Below 5px, or below
half the row height, the residue letters stop drawing, and they account for most
of the file size.
Uses#
msa-parsers for file format support, and react-msaview for rendering.
License#
MIT